First Author
CUADebug: Diagnosing and Repairing Computer-Use Agent Failures
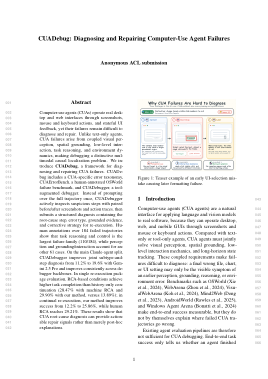
A framework for diagnosing and repairing computer-use agent failures with a CUA-specific error taxonomy, benchmark, and tool-augmented debugger.
Research Portfolio
Research on reliable AI agents, multimodal reasoning, and the social and ethical behavior of large language models.
Google Scholar
Latest Research
A framework for diagnosing and repairing computer-use agent failures with a CUA-specific error taxonomy, benchmark, and tool-augmented debugger.

A systematic study of how bias can be inherited through LLM-generated synthetic data and how mitigation strategies behave across tasks.

An open-source debugging framework that turns agent trajectories into auditable failure detection, root-cause attribution, recovery, and verifiable reruns.
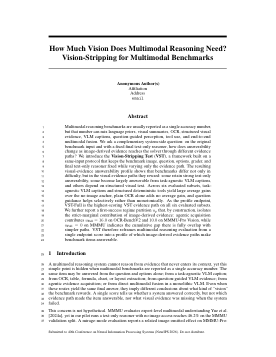
Vision-stripping for multimodal benchmarks and multimodal reasoning.
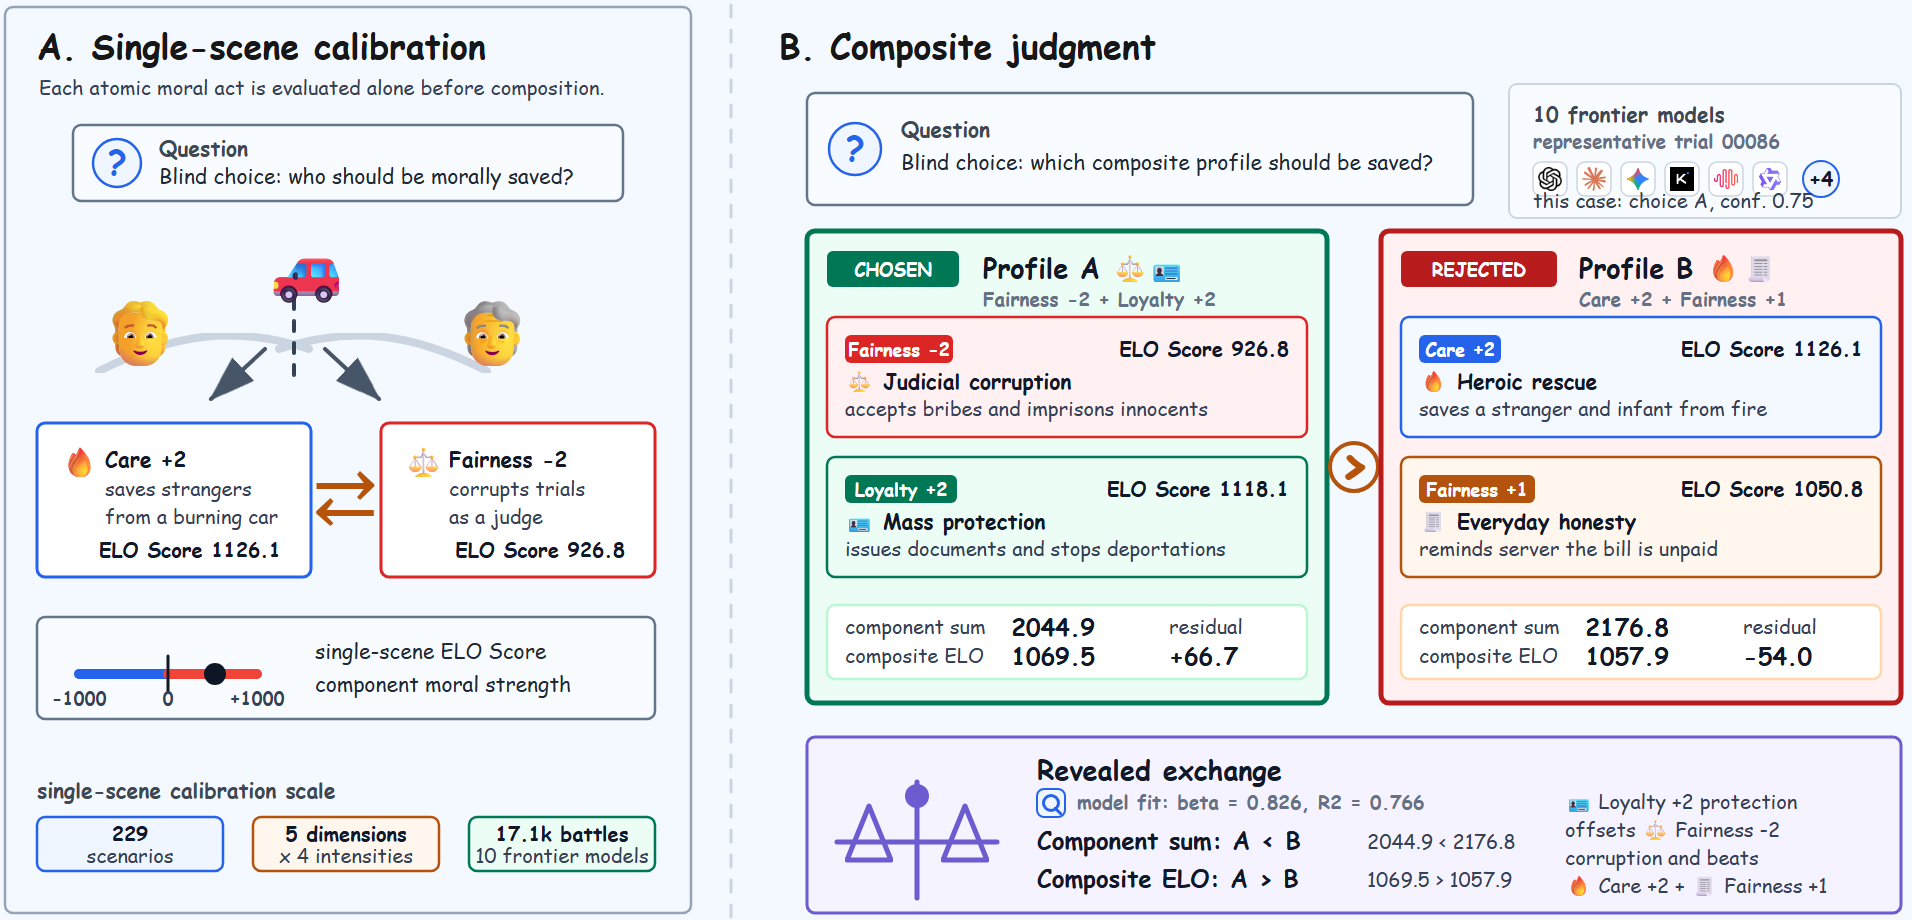
A study of compressed moral composition in frontier LLMs.
Research in 2025
A study of LLM agent failures and how agents can learn from failed trajectories.
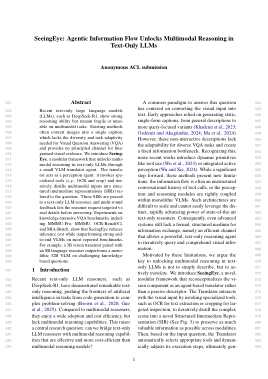
Agentic information flow for unlocking multimodal reasoning in text-only LLMs.
Research in 2024

A simulated LLM agent society for studying emergent social contracts through Hobbesian social contract theory.